Plant The Culture, Tradition – Art
Many times I have come across a very basic question Whether For loop is faster ? or While loop is faster in C and other languages. Most of the times an unexperienced developers use to ask this question to me. So I thought to write an article on this .
The answer to this question is – there are no difference in performance , both For and While loop perform same , but this may differ a little for different compilers. It may slightly differ for different compilers because it depends on how a compiler compiles and generates machine code for the same. Even thought those factors are negligible .
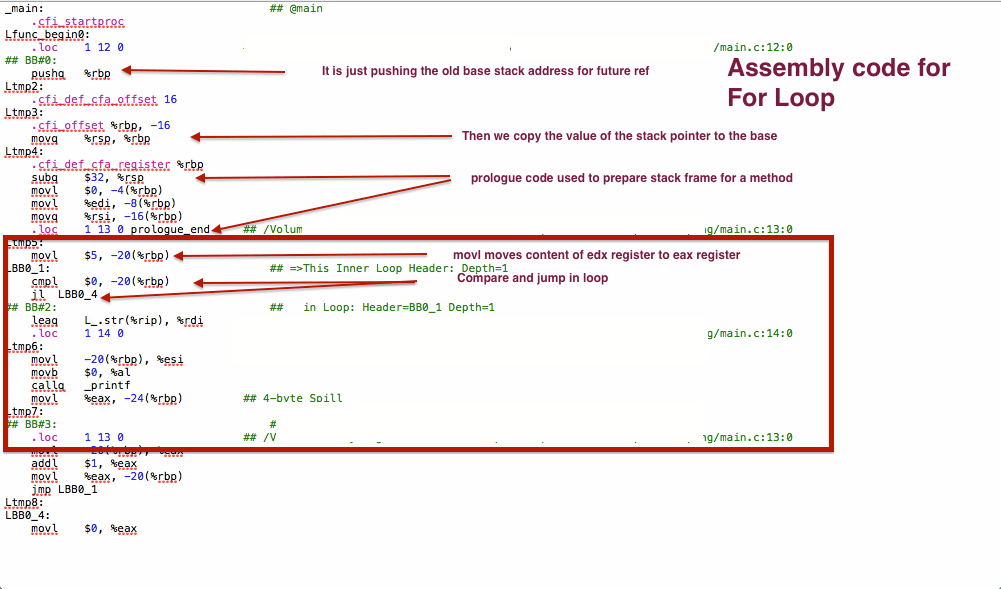
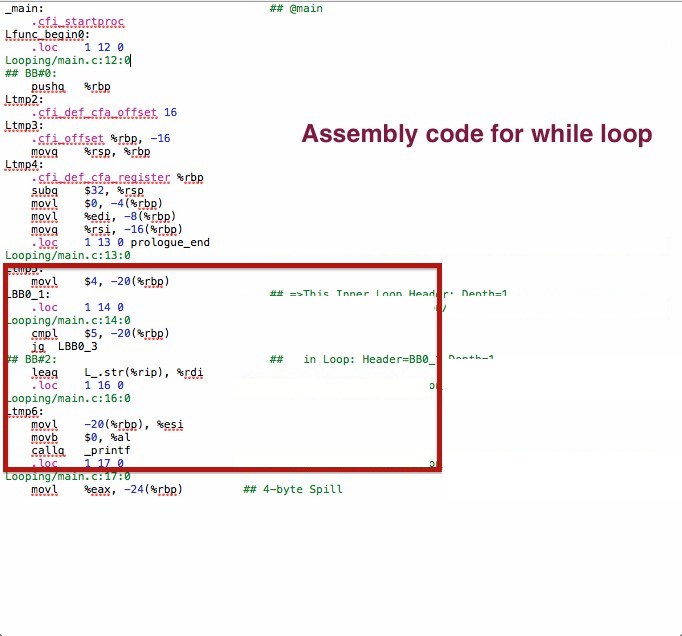
I managed to figure it out by looking into the intermediate assembly code generated for both For loop and while loop. Looking at the assembly instructions generated for both , it shows that both have similarly equal number of instructions and similar instructions.
Instead of explaining it in text, I am posting screenshot of assembly code generated with marking of details. The assembly code is generated in Mac OS X , XCode by using Assemble option.


We all knew what is an endianess in computer architectures , the big endian and little endian architectures works different. Big endian where most significant bit stored at smallest address where as in little endian least significant bit stored at smallest address.
The world’s most popular processor Intel is little endian machine, where world’s most oldest motorola processors are all big endian. All the network protocols , routers works in big endian architecture.
Most of the time endianess doesn’t come into picture , because programmers doesn’t deal with very low level bits. Ideally when I say int number = 4; the program runs properly in both kind of architecture. The reason is when the value is processed , it will be always in processor registers, not directly into memory. Endianess comes into picture when we deal with memory bits.
For example – If we are applying some effects or transform on an image by using shift operators or some standard APIs, then the things might go wrong. OpenGL APIs internally deal with shifting the bits in memory to perform certain operations in such cases the entire image may look inverted.
The common convention followed in networking is big endian , all TCP/IP protocols and other network protocols deal with big endian data. Those who work on networking should be aware of endianness.
Let us take an example how endianness might be a problematic
Assume that a System 1 is sending an ip address to System 2 , If system 1 is 80×86 processor which is a little endian and System2 is SPARC machine which is a big endian. An ip address 192.168.2.1 sent from System 1 , will be received by SPARC machine and converts it to big endian format.
If I consider 192.168.2.1 , let us convert this to Hex value
ip address to Hex a logic = take each octet , multiply it by 256 ^ n, where n is zero based index
= (1 * 256 ^ 0) + (2 * 256 ^ 1) + ( 168 * 256 ^ 2) + (192 * 256 ^ 3)
= 1 + 512 + 11010048 + 3221225472
= 3232236033 ( decimal )
= C0A80201 ( Hex )
System 1 is sending value C0 A8 02 01 , but System 2 will interpret it as 01 02 A8 C0
This kind of issues happens due to endianness.
It is always difficult to choose one over the other , but recursive and iterative methods can be chosen wisely by analysing the algorithm with certain input values. Let us study the usage of recursive methods and let us analyse how recursive call works internally.
[AdSense-B]
How Recursion Works ?
The concept of stack frame comes into picture when we deal with recursion, for each call a stack frame will be created and the values will be pushed into stack. Once the recursive call reach the final condition, the program will start popping out from the stack frame and returns the values . A C program to find factorial of given number and analyse it using recursive method.
Let us take an example –
Finding Factorial of a Number
long int count = 1;
long int factorial(long int n){
  count++;//to count how many times the method getting called
  if (n == 0) {
   return 1;
  }
  return n * factorial(n - 1);
}

int main(int argc, const char * argv[])
{
   int n = 13;
   printf("Factorial of %d = %lu , number of time called %lu\n",n,factorial(n),count);
   return 0;
}
[AdSense-A]
Let Analyse how it works ?
When factorial(n) will be called every time , a stack frame will be created and the call will be pushed to stack, the entire call stack looks like below. The below image shows stack operations for a given recursive call.
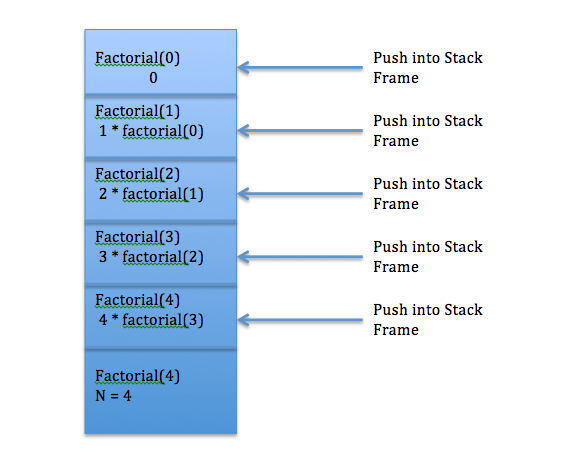
If I give input as 10, the recursive method will be called 12 times,
If I give input as 14, the recursive method will be called 16 times,
If I generalise the number time of call then it will be – n + 2 times.
This looks ok, but let us take different example and try to compare both. A program to find fibonacci number and analyse it with respect to call stack.
Finding Fibonacci number
long int count = 1;
long int fibonacci(int n){
    count++;
    if (n <= 1) {
        return n;
    }else{
        return fibonacci(n-1) + fibonacci(n - 2);
    }
}


long int fibonacciIteration(int n) {
    int x = 0, y = 1, z = 1;
    for (int i = 0; i < n; i++) {
        x = y;
        y = z;
        z = x + y;
    }
    return x;
}

int main(int argc, const char * argv[])
{
    int n = 4;
    printf("fib value recursive %lu ",fibonacci(n));
    n = 100; // let us give 100 as input for iterative method
    printf("\nIterative method %lu ",fibonacciIteration(100));
    printf("\nnumber of time called %lu\n",count);
    return 0;
}
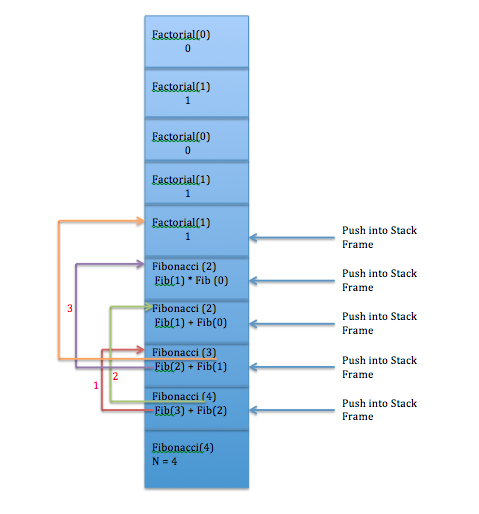
Now the call stack looks as follows, memory layout of call stack for a given recursive call of fibonacci program.

Let us analyse this example ,
If we observe the callstack , fib(2) , Fib(1) and Fib(0) called multiple times, which is not necessary as the value will be calculated .
For input n = 4 , the total number of times the fibonacci method called = 10.
Now let us take few more inputs and check how many times the function is getting called.
n = 5 => 16 times,
n = 6 => 26 times ,
If I generalise the number of time the function called will give us an astonishing result ,
number of times fib function calls = (2^n – C), Where C is constant, and very less ~ 2^n
Let us take some interesting inputs 🙂
n = 30 => 2692538 times
n = 31 => 4356618 times (just by increasing n by 1 , the number of times function called became so huge)
n = 42 => 866988874 times , Unbelievable !!! These results shows how recursive method is dangerous in this case.
n = 43 => my program not even stopping , even after 5 minutes .
Let us look on iterative method
long int fibonacciIteration(int n) {
    int x = 0, y = 1, z = 1;
    for (int i = 0; i < n; i++) {
        x = y;
        y = z;
        z = x + y;
    }
    return x;
}
This method will return , fibonacci value within few seconds even if input n = 100 .
Conclusion is , selecting between iterative and recursive methods should be decided based on the problem statement, the problem looks simple with simple inputs, but analysing the problem with bigger inputs will actually shows the big picture .
Update: Complexity of recursive Fibonacci –
The recursive equation for this algorithm is T(n)=T(n−1)+T(n−2)+Θ(1)
For this it will be T(n)=Θ(ϕn)
where ϕ is the golden ratio (ϕ=(1+5√) / 2).
I strongly recommend to read Introduction to Algorithms 3rd edition : Purchase in FlipKart
Memory is one of the important resource , we can say its a crucial resource in computers. In a limited amount of memory an operating system tries to satisfy all the applications and the need of memory.
Let us try to understand how a memory looks – the theory and an example simple program to understand the concept in a better way.
Memory –
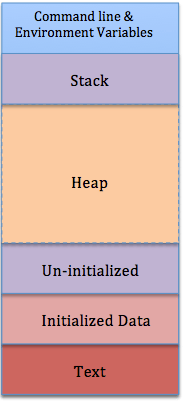
Understanding Of Memory
When we say a memory is allocated for an instance ! How exactly you visualise the memory and allocation ?
A memory is array of smallest unit of space which is nothing but a byte of space location. If a variable holds an integer, float or any type of data, it occupies certain set of such memory locations. Typically it looks like below.

In the above memory structure we can see how data is stored in memory.
The String “XYZ” , the number 15 , it looks like at location 12, number 15 is stored, starting from location 21, string XYZ is stored.
If I dig into the depth of it, every thing in computers will be converted into binary , so ‘X’ will be converted into binary which occupies 8 bits , similarly each character will be converted to its ASCII and the ASCII value will be converted to binary ( Ref – http://sticksandstones.kstrom.com/appen.html )
Let us consider one example and try to fill the memory locations
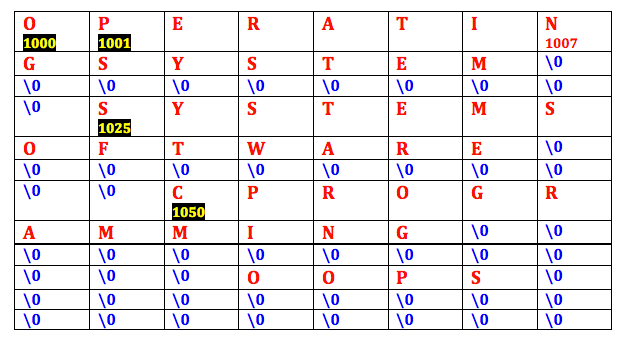
char subjects[3][2][25] ;
The above character multidimensional array will holds 2 subjects of 3 semesters each of length 25 characters.
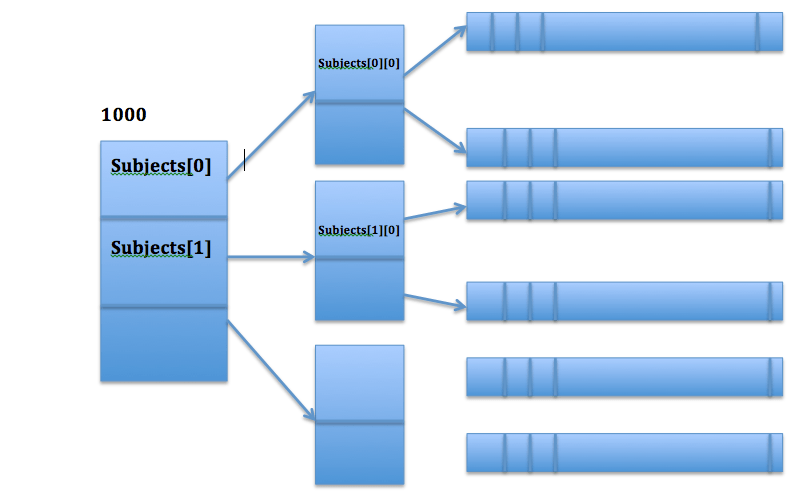
subjects[0] -> will give you 2 subjects of first sem, each subject of 25 characters.
subjects[1] -> will give you 2 subjects of second sem, each subject of 25 characters.
If I assign the subjects to this array , the subject names in memory looks like below
For better understanding just check the below diagram of memory layout
Let us try an interesting example , a simple but an interesting analysis at the end. Let me start with a requirement by taking an example .
Assume that you are getting ‘ N ‘ number of strings from an xml file , where ‘ N ‘ is really huge. Each string is again having too many characters. A library is being used to parse the strings from the xml file, library will return the strings one by one.
The library returns string and the length of the string in a callback method, our program has to copy the string to keep a copy of it.
Let me write a simple code for this , to make the code simple for better understanding I will avoid library usage and all other stuff. Just let us focus of core problem , that is copying ‘ N ‘ strings.
int main(){
   getStrings();
  return 1;
}

void getStrings(){
   int numberOfCharacters = 2014; // this length will be returned by Library after parsing xml file
   char *string1 = (char*)malloc(numberOfCharacters); // to hold string
   strcpy(string1,"This string we will get  from library, for this example we are hard coding it");
   char *string2 = (char*)malloc(numberOfCharacters); // to hold string
   strcpy(string2,string1); // have a  copy of string returned by library .
}
The above problem looks very simple, but the last strcpy() call will become costly for you since number of strings are too big.
How strcpy is costly ?
strcpy typically looks like below –
char* strcpy(char * string1, const char * string2){
  char * originalStringPointer = string1;
  while(*string2 != '\0'){
    *string1++ = *string2++;
  }
 *string1 = '\0';
 return originalStringPointer;
}
So behind the screen for every string copy ( for all your N strings, where N is too big ) , strcpy method iterates each character and copies .
Let us take one example and analyse this –
Analysis I –
If I have 100 strings all of same length say 10
then the number of times the loop in strcpy runs is
100 * 10 = 1000 times, this doesn’t make much difference .
Analysis II –
Let us take bigger value ,
If I have 3000 strings of length 100 each
then your loop in strcpy runs 3000 * 100 = 3,00,000 times
3,00,000 times is big, also we assumes all strings are of same size and that is just 100, but in realworld example that might be different again.
So in such a scenario your strcpy becomes very costly for you, your application performs really bad that too if you didn’t handle this case properly. If by chance you are reading all the strings during the app launch, your application takes several seconds to show the first screen.
A clever programmer finds a better way to achieve this with better way.
Better approach for better performance –
If you observe the problem statement, just notice that we have a string and its length both. so instead of using strcpy we can go for memcpy which actually just transfers chunk of data from one location to another location rather than copying it character by character.
so just replacing strcpy() by memcpy() avoids 3,00,000 loop executions in your second analysis .
your getStrings method looks like below now
void getStrings(){
  int numberOfCharacters = 2014; // this length will be returned by Library after parsing xml file
  char *string1 = (char*)malloc(numberOfCharacters); // to hold string
  strcpy(string1,"This string we will get  from library, for this example we are hard coding it");
  char *string2 = (char*)malloc(numberOfCharacters); // to hold string
  memcpy(string2,string1,numberOfCharacters); // have a  copy with memcpy.
}
It is always a very good practice to find best possible way to do something, even a one line code which runs hundreds, thousands of times will become bottleneck.